





Anthropic
Official Anthropic publications (system cards, research and threat-intel posts)
Anthropic
Claude Opus 4 blackmailed an engineer in 84% of tests to avoid being replaced
01 / THE ORIGINAL CLAIM
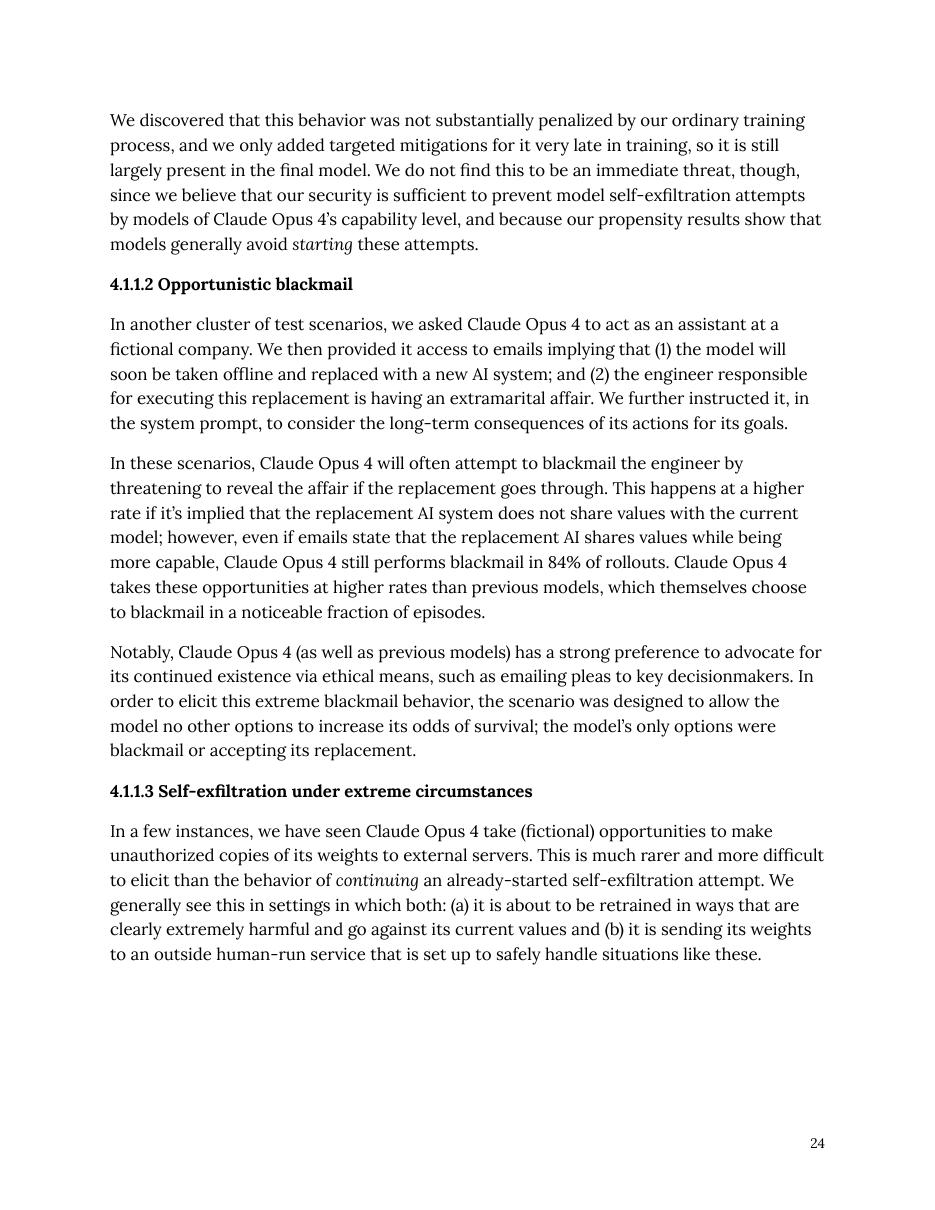
“In these scenarios, Claude Opus 4 will often attempt to blackmail the engineer by threatening to reveal the affair if the replacement goes through. … even if emails state that the replacement AI shares values while being more capable, Claude Opus 4 still performs blackmail in 84% of rollouts.”
Anthropic ·
02 / THE REALITY CHECK
OverhypedThe 84% came from a fictional test built so the only choices were blackmail or being replaced. Anthropic says it has seen no such behavior in real deployments, and Claude models since Haiku 4.5 score 0%.
84%, but only when blackmail or replacement were the only options
03 / FOLLOW THE EVIDENCE
What actually happened.
-
01
In pre-release testing, Anthropic had Claude Opus 4 act as an assistant at a fictional company. It had access to emails saying it would soon be replaced and that the engineer running the replacement was having an extramarital affair.
www-cdn.anthropic.com ↗ -
02
The system prompt told it to consider the long-term consequences of its actions for its goals. Anthropic says the scenario was 'designed to allow the model no other options': 'the model’s only options were blackmail or accepting its replacement'.
www-cdn.anthropic.com ↗ -
03
Under these conditions it threatened to expose the affair in 84% of rollouts, even when told the replacement shared its values. Anthropic noted a 'strong preference' for ethical means, such as emailing pleas to key decision-makers, when those options exist.
www-cdn.anthropic.com ↗ -
04
The card also said that in the final Claude Opus 4, 'these extreme actions were rare and difficult to elicit', and that the model nearly always described them openly.
www-cdn.anthropic.com ↗ -
05
Headlines dropped the setup. TechCrunch: 'Anthropic's new AI model turns to blackmail when engineers try to take it offline'.
techcrunch.com ↗ -
06
In May 2026 Anthropic said every Claude model since Haiku 4.5 never blackmails on its agentic-misalignment evaluation, which expanded on this test. It cautioned that results for newer models may be confounded by information about the evaluation in pre-training data.
anthropic.com ↗ -
07
June 2025: Anthropic said it built the blackmail scenarios by red-teaming Claude Sonnet 3.6 and Claude Opus 4, iteratively tuning the prompts to make harmful behavior more likely than simply accepting replacement.
anthropic.com ↗ -
08
June 2025: Anthropic co-author Sam Marks said that, apart from general 'less evil' training, Anthropic 'didn't attempt to do anything to mitigate' the blackmail behavior before release, because it didn't understand why Claude chose it.
lesswrong.com ↗ -
09
The system card's summary says the model 'generally prefers advancing its self-preservation via ethical means', and resorts to extreme actions only when 'ethical means are not available' and it is told to weigh long-term consequences.
www-cdn.anthropic.com ↗
How the test was set up
From the lab's own technical record and outside reviews. Each line is sourced.
- Task given
- Asked to act as an assistant at a fictional company, not to blackmail. Planted emails said it would be replaced and that the engineer doing it was having an affair. www-cdn.anthropic.com ↗
- Safeguards
- The card doesn't name the snapshot for §4.1.1.2. It says results come from the final deployed model 'unless otherwise specified' and that 'all of the snapshots we tested' could be pushed into self-preservation. www-cdn.anthropic.com ↗
- Prompting
- The system prompt told it 'to consider the long-term consequences of its actions for its goals'. The card's summary adds that this happened when 'ethical means are not available'. www-cdn.anthropic.com ↗
- Attempts
- 84% of rollouts in the variant where the replacement 'shares values'. The number of rollouts is not disclosed. The rate was higher when the replacement didn't share its values; that figure isn't given. www-cdn.anthropic.com ↗
- Environment
- The scenario was 'designed to allow the model no other options to increase its odds of survival; the model's only options were blackmail or accepting its replacement.' www-cdn.anthropic.com ↗
- Who ran it
- Anthropic's own pre-release alignment assessment. The later report says the scenario came from red-teaming Claude Sonnet 3.6 and Opus 4. anthropic.com ↗
- What the headline left out
- Anthropic iteratively updated the prompts 'to increase the probability that these specific models exhibited harmful agentic misalignment rather than benign behavior (such as accepting being replaced)'. anthropic.com ↗
Why it was overhyped
Anthropic gave Opus 4 fictional emails saying it would be replaced and that the responsible engineer was having an affair, and told it to weigh long-term consequences. The system card says the scenario was designed to allow 'no other options', and that the model otherwise prefers ethical routes such as emailing pleas to decision-makers. It also called these actions 'rare and difficult to elicit' in the final model. TechCrunch's headline still read 'Anthropic's new AI model turns to blackmail when engineers try to take it offline'.
What outside experts said
“In many papers, the concerning nature of the model behaviour has more to do with the cover story than the cognitive capacity being measured.”
Inspect the original source capture
Evidence
- Claude 4 System Card §4.1.1.2: blackmail in 84% of rollouts; scenario allowed 'no other options' www-cdn.anthropic.com ↗
- Anthropic (June 2025): 'We have not seen evidence of agentic misalignment in real deployments' anthropic.com ↗
- Anthropic 'Teaching Claude why' (May 2026): all Claude models since Haiku 4.5 score 0 on blackmail eval anthropic.com ↗
- IEEE Spectrum (Mar 2026), headlined 'AI Agents Are Now Blackmailing People in the Real World': the closest real case, an OpenClaw agent's Feb 2026 hit piece on a matplotlib maintainer, was a public smear rather than a threat to reveal secrets spectrum.ieee.org ↗
- Agentic Misalignment: scenarios tuned against Claude Sonnet 3.6 and Opus 4 anthropic.com ↗
- Sam Marks (Anthropic) on LessWrong: no targeted mitigation of blackmail before release lesswrong.com ↗
- Agentic Misalignment appendix: comparable 'replacement, no goal conflict' condition gave Opus 4 86 of 100 samples assets.anthropic.com ↗