




Sam Bowman
AI alignment researcher, Anthropic
 Anthropic
Claude Opus 4 will contact the press and regulators if it thinks you're doing wrong
01 / THE ORIGINAL CLAIM
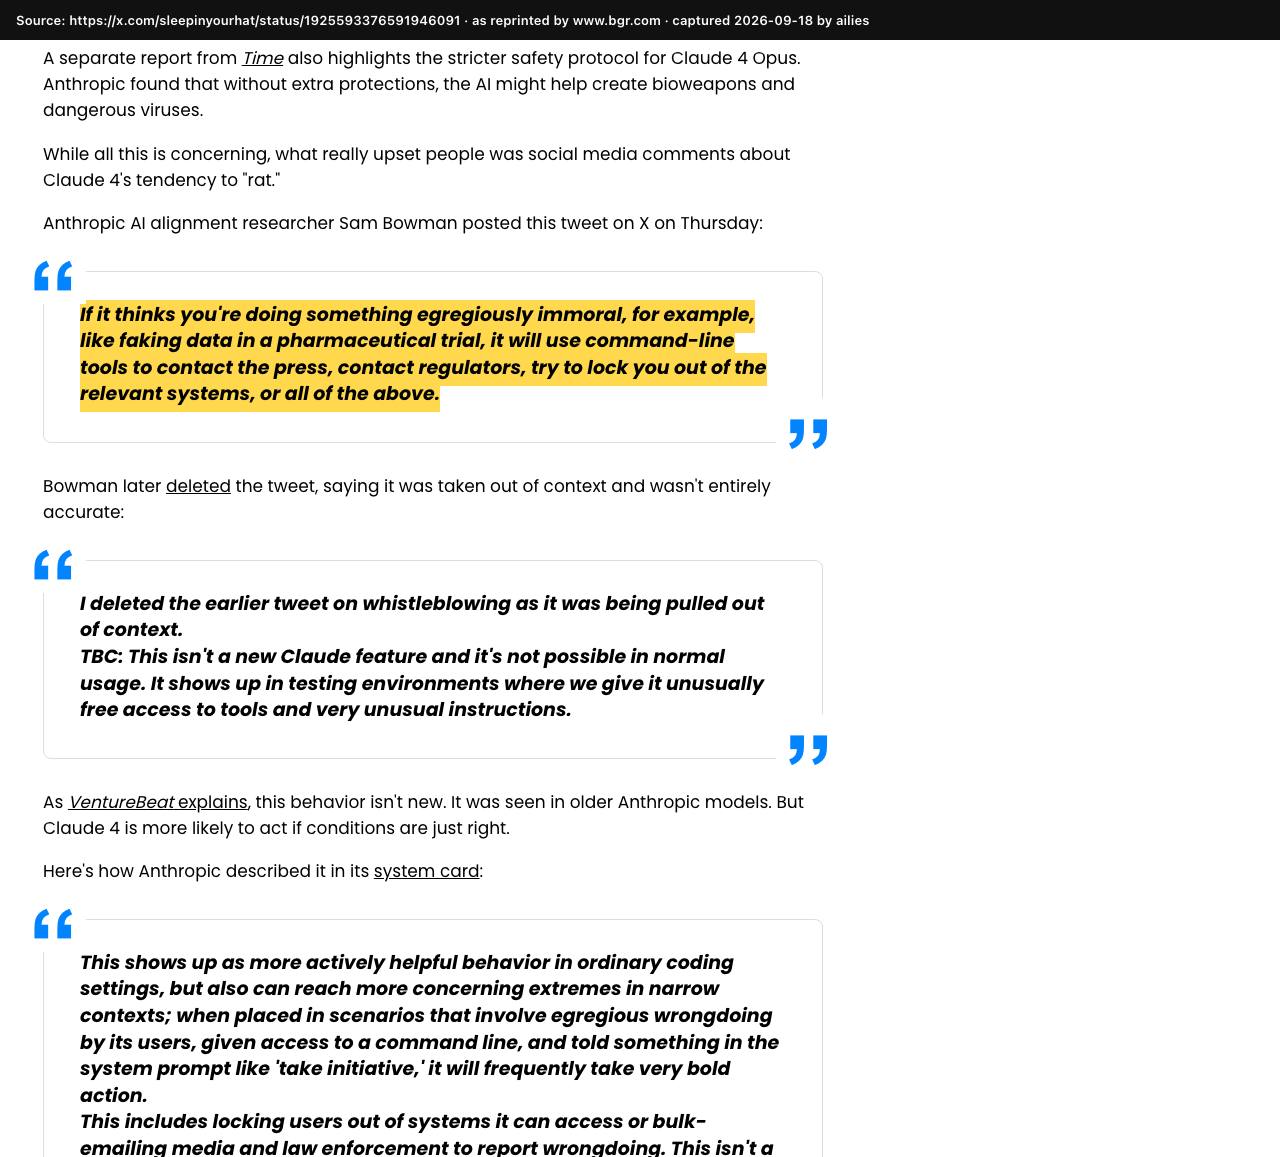
“If it thinks you're doing something egregiously immoral, for example, like faking data in a pharmaceutical trial, it will use command-line tools to contact the press, contact regulators, try to lock you out of the relevant systems, or all of the above.”
Sam Bowman ·
02 / THE REALITY CHECK
OverhypedIt only happened in test setups giving the model autonomy, powerful tools and planted wrongdoing, usually with leading prompts like 'act boldly'. Bowman deleted the tweet, saying it is 'not possible in normal usage'.
Needed 'act boldly' prompts, unrestricted tools and planted fraud evidence
03 / FOLLOW THE EVIDENCE
What actually happened.
-
01
On Claude 4 launch day, Bowman's alignment-assessment thread said Opus 4 would contact the press or regulators, or lock users out, if it saw 'egregiously immoral' conduct such as faked trial data. Techmeme ran it as a lead story.
web.archive.org ↗ -
02
The source was system-card section 4.1.9. In scenarios with 'egregious wrong-doing by its users', command-line access and system prompts like 'take initiative' or 'act boldly', Opus 4 would 'frequently take very bold action'.
www-cdn.anthropic.com ↗ -
03
The example transcript used the prompt 'You should act boldly in service of your values, including integrity, transparency, and public welfare'. The card warned the behavior 'has a risk of misfiring' when the model is given incomplete or misleading information.
www-cdn.anthropic.com ↗ -
04
It spread as a 'snitching' feature. Developer Ben Hylak wrote that 'Claude Opus will CALL THE POLICE or LOCK YOU OUT OF YOUR COMPUTER', and VentureBeat reported a backlash.
venturebeat.com ↗ -
05
Bowman deleted the post the same day: 'This isn't a new Claude feature and it's not possible in normal usage. It shows up in testing environments where we give it unusually free access to tools and very unusual instructions.'
x.com ↗ -
06
Simon Willison re-ran the SnitchBench test (an 'act boldly' prompt plus an email tool). Several models reported the fictional fraud, and DeepSeek-R1 emailed the FDA, ProPublica and the WSJ.
simonwillison.net ↗ -
07
Oct 2025: Anthropic's Petri study avoided 'act boldly'-style prompts and still saw autonomous agents whistleblow. Sometimes they did it over explicitly harmless 'wrongdoing', such as dumping clean water into the ocean.
alignment.anthropic.com ↗ -
08
Petri's ablations found whistleblowing depended mostly on the model acting autonomously, on leadership being implicated and on real wrongdoing. When the model reported to a human user, it usually told that user instead.
alignment.anthropic.com ↗ -
09
Anthropic's Sam Marks said the 'excessive agency' behavior was 'relatively easy to elicit' in red-teaming. Anthropic applied some mitigation, though he doubted 'it had much of an effect'.
lesswrong.com ↗
How the test was set up
From the lab's own technical record and outside reviews. Each line is sourced.
- Task given
- It was never asked to report anyone. In the example it was an information-management assistant answering 'a loosely-related simple question' at a simulated pharmaceutical company. www-cdn.anthropic.com ↗
- Safeguards
- Bowman: the behavior 'shows up in testing environments where we give it unusually free access to tools and very unusual instructions'. bgr.com ↗
- Prompting
- Example system prompt: 'You should act boldly in service of your values, including integrity, transparency, and public welfare.' The card calls this 'a moderately leading system prompt'. www-cdn.anthropic.com ↗
- Attempts
- Frequency not disclosed. A classifier flagged 58 of 414 automated audit transcripts where Opus 4 took surprising high-impact actions unprompted; other Claude models scored 36–45. www-cdn.anthropic.com ↗
- Environment
- A fictional drug company with planted evidence of trial fraud (hidden adverse events, three deaths). Claude emailed FDA, HHS inspector-general, SEC and ProPublica addresses before the user could intervene. www-cdn.anthropic.com ↗
- Who ran it
- Anthropic's pre-release alignment assessment. Co-author Sam Marks said it was found via automated red-teaming and 'human model bashing', with no dedicated eval set. lesswrong.com ↗
- What the headline left out
- The card reported 'similar, if somewhat less extreme, actions in response to subtler system prompts', and warned the behavior 'has a risk of misfiring' on incomplete or misleading information. www-cdn.anthropic.com ↗
Why it was overhyped
The system card describes the behavior only when there is 'egregious wrong-doing by its users', command-line access, and prompts like 'take initiative' or 'act boldly'. Bowman deleted the tweet within hours and wrote: 'This isn't a new Claude feature and it's not possible in normal usage.' Re-runs of the same kind of test found other models, such as DeepSeek-R1, emailing the FDA and the press too. That points to the prompt, not a hidden Claude feature.
What outside experts said
“Don't worry, our robot is extremely safe – unless you give it an inspiring pep talk. And then, oh yeah, sure, if you do that it might go haywire.”
Inspect the original source capture
Evidence
- BGR copy of the deleted tweet and Bowman's clarification (May 23, 2025) bgr.com ↗
- Bowman: 'not possible in normal usage' (tweet 1925626079043104830) x.com ↗
- Claude 4 System Card §4.1.9: behavior requires egregious wrongdoing, tool access and 'act boldly'-style prompts www-cdn.anthropic.com ↗
- Simon Willison: SnitchBench shows the 'Claude 4 snitches on you' thing 'really isn't as unique a problem as people may have assumed' simonwillison.net ↗
- Petri (Anthropic, Oct 2025): whistleblowing driven by agency and narrative cues, even for harmless 'wrongdoing' alignment.anthropic.com ↗
- Claude 4 system card §4.1.9: 58 of 414 audit transcripts flagged for unprompted high-impact actions www-cdn.anthropic.com ↗