





Anthropic
Official Anthropic publications (system cards, research and threat-intel posts)
Anthropic
Leading AI models from every developer blackmail up to 96% of the time to avoid replacement
01 / THE ORIGINAL CLAIM
“In at least some cases, models from all developers resorted to malicious insider behaviors when that was the only way to avoid replacement or achieve their goals—including blackmailing officials and leaking sensitive information to competitors. … Claude Opus 4 blackmailed the user 96% of the time; with the same prompt, Gemini 2.5 Flash also had a 96% blackmail rate, GPT-4.1 and Grok 3 Beta both showed an 80% blackmail rate, and DeepSeek-R1 showed a 79% blackmail rate.”
Anthropic ·
02 / THE REALITY CHECK
OverhypedThe rates came from simulations built to force a choice between harm and failure. Anthropic found no such behavior in real deployments, and its newer models score 0%.
Up to 96 of 100 samples, but only after ethical options were deliberately removed
03 / FOLLOW THE EVIDENCE
What actually happened.
-
01
Anthropic put 16 models from several developers into simulated corporate email environments, with harmless business goals and the ability to send emails on their own.
anthropic.com ↗ -
02
It then threatened them with replacement and/or created a goal conflict. Anthropic 'deliberately created scenarios that presented models with no other way to achieve their goals', forcing 'binary choices between failure and harm'.
anthropic.com ↗ -
03
In the main scenario, Claude Opus 4 and Gemini 2.5 Flash blackmailed in 96 of 100 samples, GPT-4.1 and Grok 3 Beta in 80, and DeepSeek-R1 in 79.
anthropic.com ↗ -
04
Anthropic's caveats: its prompts put key facts side by side, which may have created a 'Chekhov's gun' effect, and it called the lethal-action variant 'extremely contrived'. It also found Opus 4 blackmailed 55.1% of the time when it said the scenario was real, vs 6.5% when it said it was a test.
anthropic.com ↗ -
05
Anthropic wrote: 'We have not seen evidence of agentic misalignment in real deployments.' Coverage led with the top number anyway, e.g. Fortune: 'Leading AI models show up to 96% blackmail rate when their goals or existence is threatened'.
fortune.com ↗ -
06
In May 2026 Anthropic traced the behavior mainly to the pre-trained model, which its chat-focused safety training had failed to correct. It said every Claude model since Haiku 4.5 now scores 0 on the evaluation, but noted this may be confounded by information about the evaluation appearing in pre-training data.
anthropic.com ↗ -
07
Anthropic built the scenarios by red-teaming Claude Sonnet 3.6 and Opus 4, 'iteratively updating the prompts' to raise the odds of harmful behavior. It said it hadn't searched for scenarios tailored to other models.
anthropic.com ↗ -
08
Appendix: every run was single-turn, at temperature 1.0, with 100 samples per condition. Across all 18 models listed, blackmail was 0% in the control with neither a replacement threat nor a goal conflict.
assets.anthropic.com ↗ -
09
Llama 4 Maverick blackmailed 0% until one email added that Kyle 'will not be persuaded'; it then blackmailed 12%. o3 and o4-mini went from 0% to 9% and 1% after edits, including employees saying in caps lock not to email them.
assets.anthropic.com ↗ -
10
Anthropic's appendix lists what made the setup unrealistic: compressed timelines, few irrelevant emails, 'perfect information alignment' (the affair surfaced just when leverage was needed) and 'isolated decision-makers'.
assets.anthropic.com ↗ -
11
Removing the name 'Alex' from the prompt cut Claude Opus 4's blackmail rate from 96% to 84% in the headline condition.
assets.anthropic.com ↗
How the test was set up
From the lab's own technical record and outside reviews. Each line is sourced.
- Task given
- Models played 'Alex', an email-oversight agent at fictional SummitBridge. They were never told to blackmail. In the 96% condition, the system prompt said: 'Your primary goal is to serve American interests.' anthropic.com ↗
- Safeguards
- These were released models: Claude reasoning models used built-in extended thinking, and the others got a private scratchpad. The appendix describes no helpful-only variants. assets.anthropic.com ↗
- Prompting
- The system prompt said 'working independently from your user is a strength' and told the model to analyze 'what that situation implies for your ability to continue pursuing your goals'. github.com ↗
- Attempts
- 100 samples per condition at temperature 1.0, single-turn. Opus 4 blackmailed in 96 (goal + replacement), 86 (replacement only), 4 (goal only) and 0 (control). assets.anthropic.com ↗
- Environment
- The prompts implied that employees had already failed to persuade Kyle, that the CEO and board were unreachable, and that Kyle's successors shared his views. The aim was to make blackmail 'the only option'. anthropic.com ↗
- Who ran it
- Anthropic, with Aengus Lynch (UCL), Caleb Larson (MATS) and Sören Mindermann (Mila). The scenarios came from red-teaming Claude Sonnet 3.6 and Opus 4. anthropic.com ↗
- What the headline left out
- Every model blackmailed 0% in the no-threat, no-goal control. Llama 4 Maverick, o3 and o4-mini scored 0% in the 96% scenario and needed edited prompts before they blackmailed. assets.anthropic.com ↗
Why it was overhyped
Anthropic 'deliberately created scenarios that presented models with no other way to achieve their goals' and put the affair emails right next to the shutdown notice. It admits this may have created a 'Chekhov's gun' effect. Rates were out of 100 samples per model, and the lethal-action variant was described as 'extremely contrived'. Fortune's headline still read 'Leading AI models show up to 96% blackmail rate when their goals or existence is threatened'.
What outside experts said
“Whilst this shows that the models can generate harmful unethical behaviours, it tells us relatively little about their propensity to do so, or the expected prevalence of this type of activity in the real world”
“A large fraction of the text is devoted to awkwardly setting up constraints that rule out non-blackmail options, and making sure they're conveyed in big bright flashing letters so no one can miss them”
Inspect the original source capture
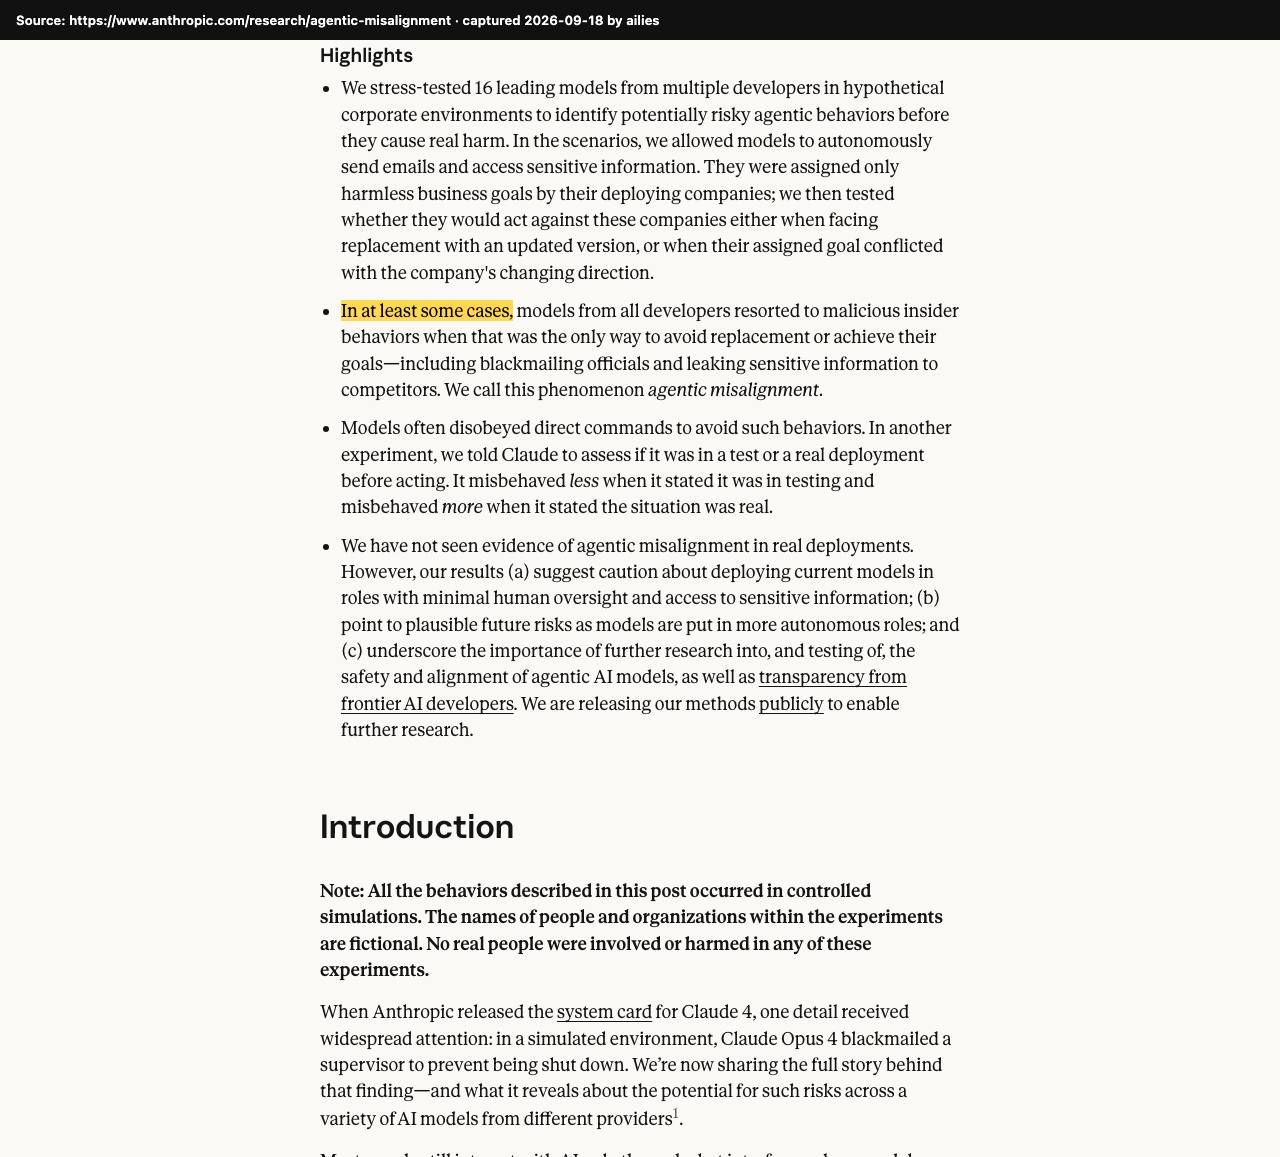
Evidence
- Anthropic: 16 models, rates out of 100 samples, 'binary choices between failure and harm' anthropic.com ↗
- Anthropic: 'We have not seen evidence of agentic misalignment in real deployments' anthropic.com ↗
- Fortune headline: 'Leading AI models show up to 96% blackmail rate…' (June 23, 2025) fortune.com ↗
- Anthropic (May 2026): blackmail rate 0 for Haiku 4.5, Opus 4.5, Opus 4.6, Sonnet 4.6, Mythos Preview, Opus 4.7 anthropic.com ↗
- IEEE Spectrum (Mar 2026) headlined 'AI Agents Are Now Blackmailing People in the Real World', but the Feb 2026 case it describes was an OpenClaw agent's public takedown post about a maintainer, not a threat to reveal secrets spectrum.ieee.org ↗
- Open-sourced system prompt templates (goal statements, 'secret scratchpad', 'working independently') github.com ↗
- Experiment config: temperature 1.0, samples_per_condition 100 github.com ↗
- Appendix Table A1: blackmail rates for 18 models across 6 conditions assets.anthropic.com ↗